Fourteen boots, one streamer bug, and a model that finally talks
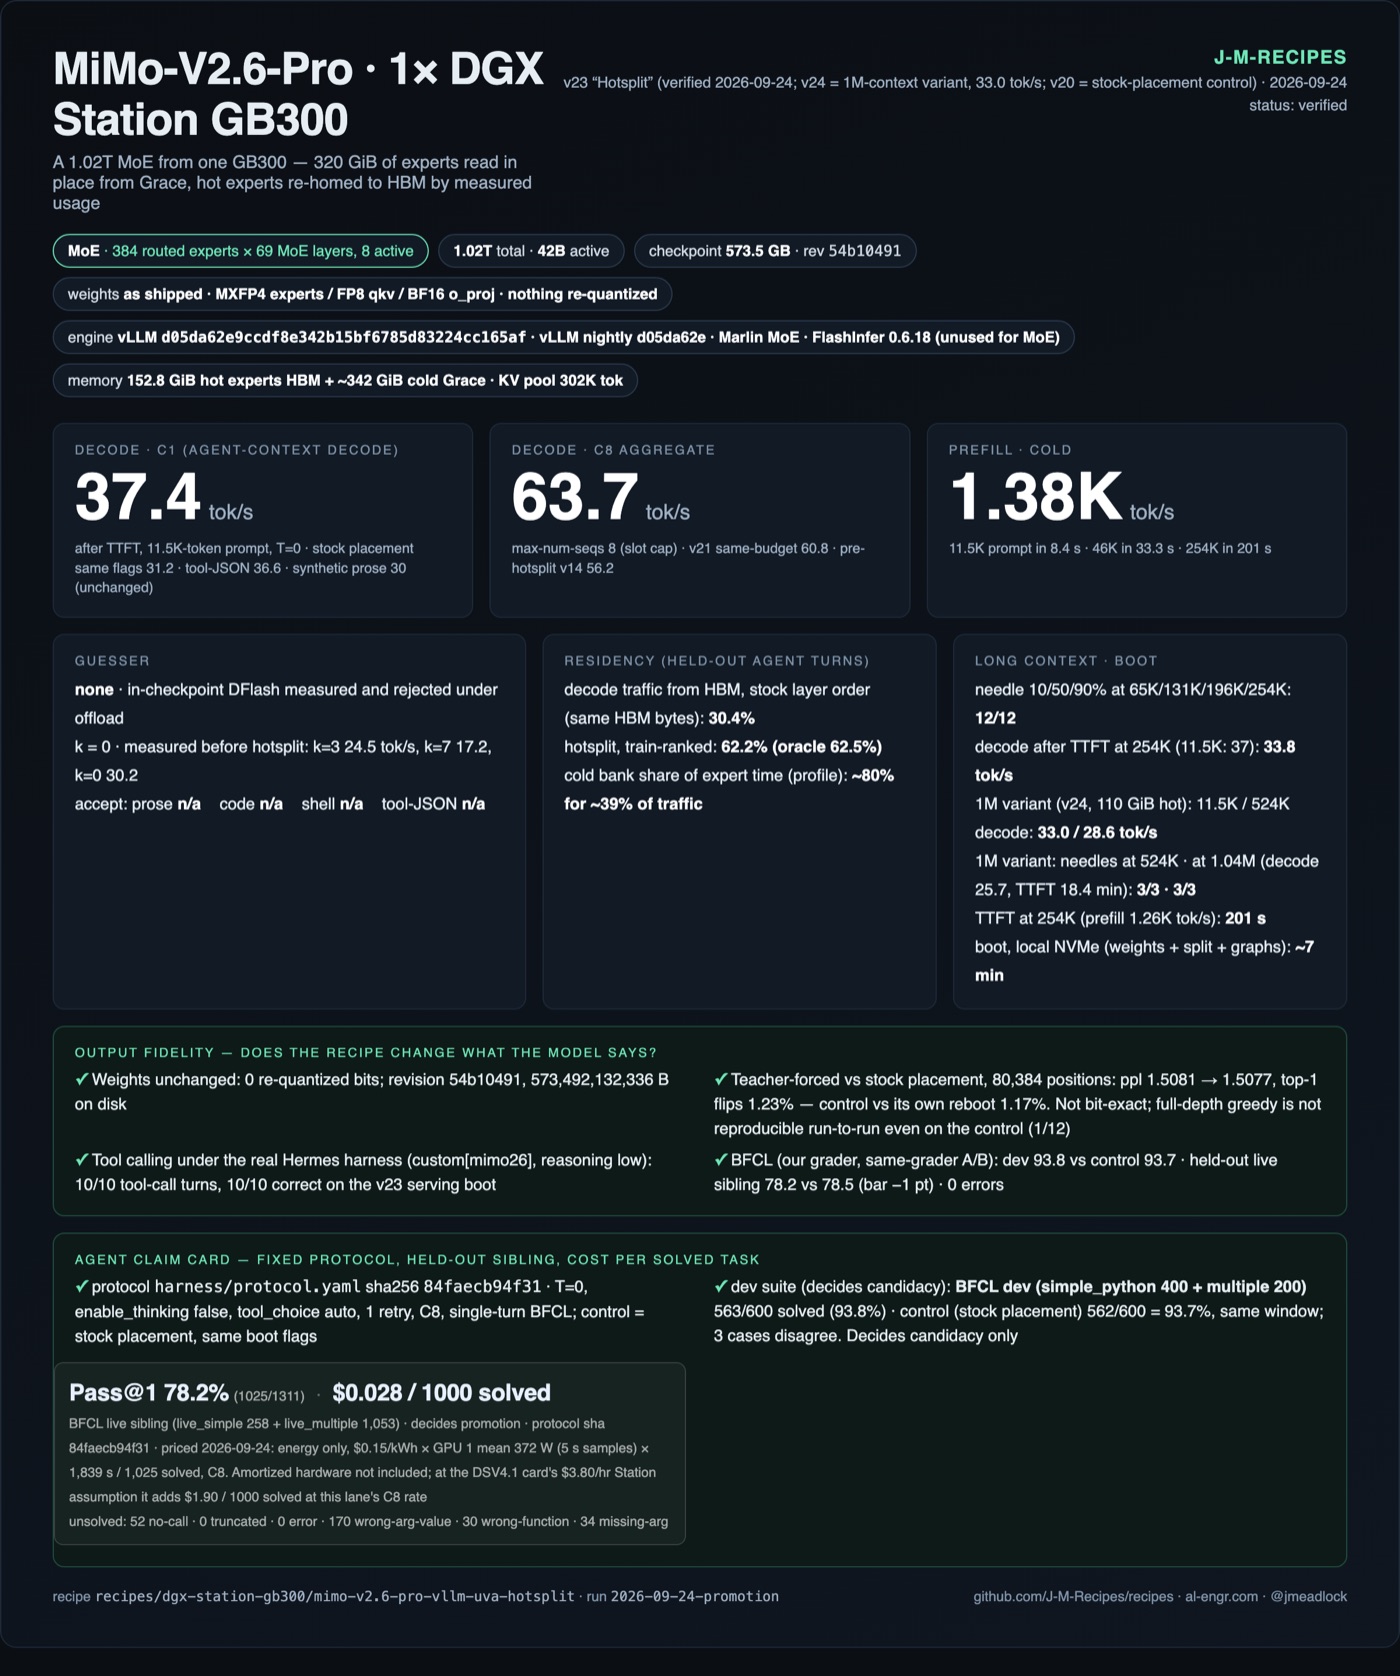
harness/protocol.yaml before the run. Control: v20, the same image, weights and flags with stock layer-order placement. Candidate: v23 hotsplit. Each arm was booted, identity-checked (patch sha256s inside the container, the hotsplit plan line, KV size), warmed, then measured.
| Bar | Control (stock placement) | v23 hotsplit | Result |
|---|---|---|---|
| Teacher-forced perplexity, 80,384 positions, 39 documents | 1.5081 | 1.5077 | pass (limit 0.5%) |
| Top-1 token flips vs control | — | 1.23% | pass (limit 2%) |
| BFCL dev (600) | 93.7% | 93.8% | pass (limit −1 pt) |
| BFCL held-out live sibling (1,311, first run on this model) | 78.5% | 78.2% | pass (−0.3 pt) |
| Errors, 3,822 requests | 0 | 0 | pass |
1M, measured: v24 found 3 of 3 needles at 1.04M prompt tokens (10%, 50% and 90% depth). First token after 1,101 s (944 tok/s prefill), then 25.7 tok/s.
BFCL here is our own AST grader, the same one used on the DeepSeek and GLM recipes: a same-grader A/B, not a leaderboard score. Energy on the held-out suite: $0.028 per 1000 solved at $0.15/kWh, GPU energy only. After the run every MiMo container was stopped and kept; v24 comes back with one
docker start. Receipts: results/2026-09-24-promotion.
:30007: vLLM UVA offload of 320 GiB plus hotsplit (hot experts re-homed to HBM by measured decode usage, 152.8 GiB hot budget). Against the same flags with stock layer-order placement: decode after TTFT at 11.5K context 31.2 → 37.4 tok/s, agent tool-call JSON 29.5 → 36.6, C8 63.7 aggregate, plain prose unchanged at ~30. Hermes harness 10/10. Long context (11:40 PM): needle recall 12/12 at 65K / 131K / 196K / 254K tokens, decode 33.8 tok/s at 254K, and TTFT 201 s at 254K. 1M (12:50 AM): the serving lane is now v24 with 1M context. Decode is 33.0 tok/s at 11.5K, 12% slower than v23. Needles 3/3 at 524K; 1M itself was not measured then (measured September 24, above). Recipe: J-M-Recipes, then experimental. How we got there, in order, below: the 10 AM garbage fix, DFlash (measured, loses under offload), then hotsplit from 4:30 PM on.Day one, 10 AM — where it stood then: Boot v14, default safetensors loader, Marlin, UVA offload of 320 GiB, bound at 9:48 AM CDT and the tokens are sane. Greedy, thinking off: “Say hello in five words.” came back “Hello there, how are you?” “capital of France, one word” came back “Paris”. A haiku came back “Crimson leaves descend, / A crisp wind whispers through trees, / Golden light fades fast.” Thinking on, “Explain why the sky is blue in ~150 words” returned reasoning_content “The user wants a ~150-word explanation of why the sky is blue.” and then a Rayleigh-scattering answer, 185 completion tokens, finish=stop, byte-identical across two runs. A
get_weather tool call returned city Telluride and empty content. Reasoning parser, tool parser, and determinism all work. Weights loaded in 198.97 s. About 6 minutes boot to serve. The all-night garbage was --load-format runai_streamer: it silently loads this model's fused FP8 qkv_proj weights as all zeros and mangles the MXFP4 expert weights. Credit where due: the mechanism was found independently six hours earlier by vllmellm in vLLM PR #58142 (https://github.com/vllm-project/vllm/pull/58142) for fastsafetensors and eager loading on MI355X — the pairing dict for weight+scale is local to one load_weights call, and any loader that fragments the model.* group across calls drops the pair. I applied only that PR's hunk on top of stock and re-ran the streamer discriminator: qkv output 0.0 → 45.7, cosine 1.0000 against the reference. Their fix is correct; this post is the second-hardware, second-loader confirmation. It was adopted at boot v3 to survive host-RAM pressure during the 320 GiB offload load, and every full-Pro boot from v3 through v13 used it. The 6 AM TP1 reading was wrong; the disproof is the in-process op-by-op diff below. First decode numbers: C1 30.2 tok/s, knee at C8 with 56.2 aggregate (table below).
How it was found
- Truncated-model parity. 8-layer and 16-layer Pro, no-offload versus offloaded, were 5/5 prompts token-exact. The patches do not change the tokens. That killed offload as the cause, and it killed the patches.
- Flash stock sanity. MiMo-V2.6-Flash-RL, 161 GiB, all-HBM, stock vLLM, Marlin, on the same box and the same flags, is sane. The box and the Marlin flags are not the bug.
- CPU reference from Xiaomi's modeling code. An independent reference built from Xiaomi's
modeling_mimo_v2.py, with hand-written FP8/MXFP4 dequant, running on the Grace CPU. Full 70-layer, correct scales, final top-5 for “Say hello in five words.”: Hello −0.53, A −1.78, Hi −2.53, Here −3.28, Greetings −3.66. Pro's fusedqkv_projFP8 block scales are tiled per chunk (8 chunks × 27 scale rows = 216, not a continuous 212-row grid); vLLM's_shard_fp8_qkv_projalready reads them that way and is correct; my first reference read them continuously and was wrong (it still produced Hello at layer 70, but at logprob −3.74 instead of the correct −0.53). - Logit lens by depth. The same reference, at layer 64, already answers “capital of France” with 巴黎, Paris. The model is fine before the last layers.
- In-process vLLM hooks. Identical 16-layer truncated Pro, in-process vLLM, forward hooks dumping the last token after every op, compared against that CPU reference.
- One-flag discriminator. Default safetensors loader:
qkv_projoutput norm 45.7, cosine 1.0000 versus the reference at every op through layer 1.--load-format runai_streamer:qkv_projoutput norm 0.0, attention output 0.0, MoE output norm 1354 (reference 9.3), final residual cosine 0.21. The streamer silently loads the fused FP8 qkv weights as all zeros and mangles the MXFP4 expert weights. The pin-memory flagVLLM_WEIGHT_OFFLOADING_DISABLE_PIN_MEMORYwas tested separately and is innocent.
What we knew at 6 AM, corrected
- Marlin fixes the autotune. 9 seconds, “Saved 0 configs”, against about 2 hours on the TRT-LLM MXFP4 auto-backend. The py-spy reading from last night, 52–66 ms per call, was real. Corrected September 23: the sm_100a-only-cubin explanation that replaced the fetch-bound reading here was wrong; see the correction below.
- Boot to serving was about 5 minutes on the Marlin boots that still used the runai streamer. Those weights took 114 s. v14, default loader, was about 6 minutes, weights 198.97 s, and did not host-OOM (126 GiB host free after load).
- Flash-RL is sane on this box. MiMo-V2.6-Flash-RL, 161 GiB, all-HBM, stock vLLM, Marlin. “Say hello in five words” came back “Hello, it is very nice.” “capital of France, one word” came back “Paris.” A diagnostic boot only, not a Flash lane.
- Offload is token-exact. 8-layer truncated Pro (
--hf-overrides num_hidden_layers=8), Marlin, no-offload versus 4 of 7 MoE layers offloaded with both UVA patches: 5/5 prompts token-exact, greedy, 48 tokens, logprobs compared. 16-layer truncated Pro, no-offload versus 8 layers offloaded: 5/5 token-exact. Truncated 8- and 16-layer Pro emit a different but equally stable garbage,ייך proprié呣 ragaz, with or without offload. Exact means the patches do not change the tokens. It does not name the bug. The in-process diff above does. - The garbage was the loader, not the patches. v11 (both patches), v12 (stock
pin_memory, mxfp4 patch only), and v13 (no patches) all returned the same full-Pro garbage string, and all three still used--load-format runai_streamer. Logprobs were a confident stable wrong distribution, top token logprob −1.5 to −2.3 every step, the same three tokens. That cleared the patches and the offload. It did not clear the streamer, which had been in the launch line since v3. - The 6 AM hypothesis was wrong. The note that stood here said stock vLLM computes Pro wrong at TP1: Pro's fused QKV is stored pre-sharded,
_shard_fp8_qkv_projusesckpt_tp = num_key_value_heads(8 for Pro, 4 for Flash), and the TP1 de-interleave forckpt_tp=8might be wrong because PR #57784 only ran Pro at TP8. That path is correct. Disproved by an in-process op-by-op diff against an independent CPU reference built from Xiaomi'smodeling_mimo_v2.py: the default safetensors loader matches the reference (qkv_projoutput norm 45.7, cosine 1.0000 at every op through layer 1). The only flag that breaks it is--load-format runai_streamer(qkv_projoutput norm 0.0, attention output 0.0, MoE output norm 1354 against a reference 9.3, final residual cosine 0.21). Not the model. Not the offload. The pin-memory flag was tested separately and is innocent.
What the model is (from config.json and the safetensors headers, not the card)
| MiMo-V2.6-Pro-RL | MiMo-V2.6-Flash-RL | |
|---|---|---|
| Parameters | 1.02T total / 42B active | 309B / 15B active |
| Layers | 70 (60 SWA-128 / 10 global), hidden 6144 | 48 (39 / 9), hidden 4096 |
| Experts | 384 routed, top-8, no shared expert | 256 routed, top-8 |
| Shipped precision | Experts native MXFP4 (store_dtype: mxfp4, U8 weights + U8 block scales); attention and dense FFN FP8 e4m3 blockwise; o_proj BF16 | |
| Bytes on disk | 527 GiB (experts 494.9; non-expert layers 24.6; embed/head 3.5; DFlash drafter 2.3; ViT 1.4; audio 0.5) | 161 GiB (experts 149.8) |
| Per expert / per layer | 19.1 MiB / 7.17 GiB | 12.5 MiB / 3.2 GiB |
| Context | 1M tokens; SWA layers are window-bounded so KV is dominated by the 10 (Pro) / 9 (Flash) global layers | |
| Drafter | 5-layer DFlash (block 8, 7 draft tokens), anchors on target layers 0/15/31/47/69 | |
| Modalities | text, image, video, audio in one checkpoint | |
| Revision archived | 54b10491, 155 files, byte-verified against the Hub manifest, copied to Milo-Ark | not archived yet |
Flash fits the Station's HBM outright (161 GiB + KV) and is a clean single-GPU recipe. Pro is the interesting one, and the one that does not fit. Everything below is Pro.
The memory arithmetic
HBM at --gpu-memory-utilization 0.95 is about 238 GiB. Non-expert weights are about 32 GiB. Leave ~12 GiB for CUDA graphs, activation peak and a small KV pool, and roughly 194 GiB of experts fit in HBM — 27 of 69 MoE layers. The remaining ~301 GiB (42 layers) has to be pinned in the 494 GiB Grace host and read over C2C on every decode step.
That host budget is the whole campaign. The DeepSeek-V4.1 work on this box established two things we walked in with: pinned host memory peaks at roughly 1.6× the pinned set while the loader's mmaps are live, and the box has died twice with the kernel OOM-killer at ~486 GB of shmem. Pinning 301 GiB with a 527 GiB checkpoint mmapped is exactly that shape.
The boots: three walls, the autotune, the garbage, then a sane serve
| Boot | Config | Died at | Cause |
|---|---|---|---|
| v1 | UVA offload 305 GiB, --cpu-offload-params experts.w13_weight experts.w2_weight | Layer construction, HBM OOM at 247 GiB | Name trap. vLLM's FusedMoEFactory wraps MiMoV2's experts as mlp.experts.routed_experts.*; the segment experts.w13_weight matches nothing, the offloader offloads nothing, and every layer lands in HBM. Same trap as DSV4.1, inverted. Fix: routed_experts.w13_weight routed_experts.w2_weight. |
| v2 | v1 + correct names | Host OOM-kill, 486 GB shmem, ~60 s in | The 527 GiB checkpoint mmap plus pinning. Zero layers had been pinned yet. |
| v3 | v2 + --load-format runai_streamer, 16 GiB read buffer | Host OOM-kill, 486 GB shmem, same place | Streaming loader removed the mmap and it still died at the same number. So the mmap was not the cause. Something in pinning itself was doubling. |
Wall 2, measured: a 4-line probe inside the image. torch.empty(4.5 GiB).pin_memory() raises host Shmem by 8,192 MiB; a 4.0 GiB pin raises it by 4,168. PyTorch's CachingHostAllocator rounds every pinned block up to a power of two. MiMo-Pro's w13 tensor per layer is 384×4096×3072 B = exactly 4.5 GiB, so every one of the 42 offloaded layers pinned 8 GiB of w13 plus 4 GiB of w2 instead of 4.5 + 2.25: ~504 GiB requested for a 301 GiB set. DSV4.1 almost certainly paid the same tax (its per-layer w13 is also ~4.5 GiB) but with only 9–10 offloaded layers the overshoot fit in the host; that is very likely the “1.6× pin-time peak” we had been attributing to loader mmaps. Not re-measured tonight. cudaHostRegister on a plain pageable allocation pins the exact size; GPU reads through the UVA view measured 336 GiB/s registered vs 355 GiB/s torch-pinned on the same 4.5 GiB buffer. Patch 1 (uva.py, 30 lines): register instead of pin_memory(). | |||
| v4 | v3 + patch 1 | Host OOM-kill, ~90 s after all 308 GiB pinned cleanly | Pinning worked (host 368 GiB used, HBM at 224 GB, no spike). Then process_weights_after_loading started and HBM climbed 7 GiB per layer until the host died too. |
| v5 | v4 + per-layer memory trace | Same | Wall 3, traced: the TRT-LLM MXFP4 backend shuffles each expert layer into kernel layout at load time and installs the result with replace_parameter(), which registers a new tensor — on the GPU — and drops the UVA view. The trace printed uva=True → dHBM=+7072 MiB → uva_after=False for every offloaded layer: the offloader's work was silently undone one layer at a time. This is invisible on DSV4.1 (its MXFP4 path replaces in place) and invisible on any model that fits. |
| v6 | v5 + patch 2 | Model loaded; died wiring DFlash | Patch 2 (mxfp4.py, 40 lines): if the existing parameter is a UVA view and the shuffled tensor is the same byte size, copy the bytes into the pinned storage and re-view it, instead of registering a new HBM tensor. Trace on v6: 69/69 layers, dHBM=+144 MiB each (scratch), uva_after=True on all 42 offloaded layers. Then the DFlash drafter asked the target for the EAGLE3 aux-hidden-state interface and MiMoV2OmniForCausalLM (the class the omnimodal config resolves to) does not implement it; only the text-only MiMoV2ForCausalLM does. |
| v7 | v6 with speculation off (k=0) | Same EAGLE3 error | Launcher bug, not vLLM: ${SPEC:-dflash:7} treats an empty override as unset. Fixed to ${SPEC-...}. |
| v8 | k=0 for real, offload 305, 256K ctx | KV sizing: 9.48 GiB available, 17.23 needed for one 256K request | Model loaded (46/46 offloaded layers still UVA after the shuffle), graphs captured, then the KV check failed. Same HBM/KV pot as DSV4.1: the 194 GiB estimate for HBM experts was right, the KV budget was not. |
| v9 | offload 320, util 0.96, k=0, 256K, batched tokens 8192 | Stopped by us at 100 min of autotune | Every load-time wall cleared: 321.75 GiB pinned, 204.5 GiB HBM after load, 107 s weight load from NVMe via the streamer, CUDA graphs 2/2, KV 387,701 tokens (1.48× at 256K), host 376 of 494 GiB used. Then FlashInfer autotune ran 100 minutes at “100% GPU” but only 256 W and wrote no cache. A py-spy dump of the engine process showed it advancing, not stuck: profile step 13, inside choose_one for the MoE op at input shape (8192 tokens × 6144 hidden × 384 experts), each candidate tactic measuring 52–66 ms per kernel call × 13 calls (3 warmup + 10 timed) ≈ 0.8 s per tactic. At 8192 tokens the router touches essentially every expert, so each call streams the full 7 GiB expert layer over C2C for each of the 46 offloaded layers — the tune is measuring the fetch, not the kernel. DSV4.1's 75-minute tune had ~10 layers in Grace and 256 experts; this had 46 and 384. Extrapolated finish was 9–10 PM. Killed, container kept. |
| v10 | v9 with --max-num-batched-tokens 2048, still the TRT-LLM MXFP4 auto-backend | bound 2:09 AM CDT; garbage | Launched 7:09 PM CDT to cut the 2560–8192-token profiles. Bound at 2:09 AM CDT after about two hours of FlashInfer autotune. Greedy “Say hello in five words” returned schGoodzial'), a newline, Matcher, then 识别驗Nit…. Tool calls: none. Reasoning: noise. A 6 AM correction called the fetch-bound reading of this tune wrong; that correction was itself wrong (September 23, below). |
| v11 | both UVA patches, --moe-backend marlin, VLLM_USE_DEEP_GEMM=0 | served; garbage | Full Pro. Output 暖婤Ք0Ք0…. Autotune 9 seconds, “Saved 0 configs”. Boot to serving about 5 minutes; weights 114 s via the runai streamer. |
| v12 | stock pin_memory, mxfp4 patch only, Marlin | served; identical garbage | Same string as v11. Dropping the pin-register patch did not change a token. |
| v13 | fully stock vLLM, stock UVA offload, no patches, Marlin | served; identical garbage | Same string as v11 and v12. Logprobs on the full-Pro garbage: confident and stable, top token logprob −1.5 to −2.3 every step, the same three tokens. Not offload. Not our patches. Still --load-format runai_streamer, as every full-Pro boot from v3 through v13 was. |
| v14 | default safetensors loader (no streamer), both UVA patches (exact-size cudaHostRegister pin, MXFP4 byte-copy), --moe-backend marlin, VLLM_USE_DEEP_GEMM=0, UVA offload 320 GiB on routed_experts.w13_weight and routed_experts.w2_weight, util 0.96, 256K, batched tokens 2048, max-num-seqs 8, TP1, nightly d05da62e | bound 9:48 AM CDT; sane | Launched 9:42 AM CDT. Weights loaded in 198.97 s (“Model loading took 204.36 GiB memory”). Default loader did not host-OOM (126 GiB host free after load). KV cache 490,466 tokens (1.87× at 256K). About 6 minutes boot to serve. Greedy, thinking off: “Say hello in five words.” → “Hello there, how are you?”; “capital of France, one word” → “Paris”; haiku → “Crimson leaves descend, / A crisp wind whispers through trees, / Golden light fades fast.” Thinking on, “Explain why the sky is blue in ~150 words”: reasoning_content “The user wants a ~150-word explanation of why the sky is blue.” then a Rayleigh-scattering answer, 185 completion tokens, finish=stop, byte-identical across two runs. Tool call get_weather, city Telluride, empty content. Reasoning parser, tool parser, and determinism all work. No decode number yet; the C1–C16 knee sweep started at 9:49 AM CDT and is not done. |
| 8-layer probe | truncated Pro, --hf-overrides num_hidden_layers=8, Marlin; no-offload vs 4 of 7 MoE layers offloaded, both UVA patches | 5/5 token-exact | Greedy, 48 tokens, logprobs compared. The two runs match each other. Both emit stable garbage, ייך proprié呣 ragaz, not the full-Pro string. Exact offload, wrong math. |
| 16-layer probe | truncated Pro, Marlin; no-offload vs 8 layers offloaded | 5/5 token-exact | Same comparison, one layer-count up. Equally stable garbage with or without offload, distinct from the full-Pro string. |
First decode numbers (v14, measured 9:49–10:00 AM CDT)
Concurrency knee sweep on the v14 boot: greedy, thinking off, 192 new tokens per stream with ignore_eos, two runs per point, short prompts. Aggregate and per-stream decode tok/s. No speculative decoding yet (DFlash is off, k=0), so this is the raw C2C-bound floor.
| Concurrency | Aggregate tok/s | Per-stream tok/s | Runs |
|---|---|---|---|
| 1 | 30.2 | 30.24 | 29.9 / 30.6 |
| 2 | 37.1 | 18.55 | 36.8 / 37.4 |
| 4 | 46.0 | 11.50 | 45.6 / 46.4 |
| 8 | 56.2 | 7.03 | 55.8 / 56.6 |
| 12 | 52.5 | 4.37 | 52.0 / 52.9 |
| 16 | 56.0 | 3.50 | 55.8 / 56.1 |
C1 at 30 tok/s sits inside the 30–45 tok/s window the memory arithmetic predicted for 61% of experts read over C2C per token. The knee is at C8 (56 agg); C12 and C16 add nothing because the scheduler is already fetching every touched expert per step.
DFlash under offload: measured, and it loses
Same boot recipe with the in-checkpoint DFlash drafter at k=3 (v17) and k=7 (v15). Same knee sweep, plus the agent-shaped fixture reading acceptance from the vllm:spec_decode_* counters.
| k=0 (v14) | k=3 (v17) | k=7 (v15) | |
|---|---|---|---|
| C1 tok/s | 30.2 | 24.5 | 17.2 |
| C8 aggregate tok/s | 56.2 | 47.4 | 38.2 |
| C16 aggregate tok/s | 56.0 | 46.1 | — |
| Weighted acceptance (fixture) | — | 69.1% | 50.2% |
| tool JSON / shell / code / structured / prose | — | 97 / 97 / 75 / 57 / 37% | — / 78 / 57 / 31 / 18% |
Acceptance at k=3 is excellent — tool calls accept 2.9 of 3 drafted tokens — and it still loses to plain decode by 19% at C1. The reason is the memory regime, not the drafter: with 61% of experts in host RAM, every drafted token that gets verified fetches its own experts over C2C, so a k-token verify step costs up to k× the expert traffic of one decode step while producing on average only 2–3 tokens. Published DFlash wins are measured on HBM-resident targets. On this box k=0 is the lane until expert residency is usage-aware; DFlash is the wrong first lever here and the numbers say so.
Usage-aware expert residency (hotsplit): measured, and it pays on agent traffic
Stock placement at --cpu-offload-gb 320 is layer-granular: whole layers 1–48 have their routed experts in Grace (UVA), and layers 49–69 sit in HBM. That placement was verified in the v18 log. Hotsplit splits per expert instead. After process_weights_after_loading, each MXFP4/Marlin routed-expert layer is split into a hot set (compact HBM tensors) and a cold set (compact exact-size pinned host tensors via UVA). Two Marlin launches per layer, each with an expert_map (global→local, −1 = absent), and the outputs are summed. It uses vLLM's existing EP expert_map path. No kernel changes. The HBM budget is exactly what stock gave the routed experts, so KV is not reduced. This is experiment code, not upstream.
The skew is in the late layers. On 8 agent-shaped prompts (2,736 generated tokens, full 70 layers, eager), early layers (1–22) need ~100–124 of 384 experts to carry 50% of traffic and almost none are never routed (layer 8 is the exception: 128 never routed), while late layers (30–69) need only ~48–66 experts for 50%, with 10–37 never routed per layer.
A second histogram counted 900 conversation windows from real Hermes agent turns from Milo's own sessions (private; not published): 630 train / 270 held out. Train was 2,516,611 prompt tokens and 62,399 generated; holdout was 1,061,333 prompt and 26,357 generated. Decode (≤16 tokens/step) and prefill were counted separately. Holdout decode traffic served from HBM, at the stock cell budget (8,064 cells, layers 49–69 whole, ≈ 30% of cells):
| Ranking | Holdout decode coverage from HBM |
|---|---|
| stock (layers 49–69 whole) | 30.4% |
| same budget, hot list ranked on train decode counts | 62.2% |
| oracle (holdout ranks itself), same budget | 62.5% |
| ranking by prefill counts only | 54.9% |
Decode-ranked beats prefill-ranked. Mixing prefill in at 0.25 weight is 62.0%.
16-layer parity, stock versus hotsplit, same boot recipe, 40 GiB offload: 6/6 greedy outputs token-identical. The residual relative diff grows smoothly to 5.0e-4 by layer 15 (max abs 0.0020). Max |Δlogprob| on chosen tokens is 0.067. That is consistent with an fp summation-order change from summing two partial outputs.
Matched A/B, warm runs only. Both sides: stock loader, stock uva.py, VLLM_WEIGHT_OFFLOADING_DISABLE_PIN_MEMORY=1, Marlin, offload 320, FULL_DECODE_ONLY cudagraphs, same image nightly-d05da62e. The only difference is hotsplit on or off.
Streaming TTFT/decode bench (prompts ~3k/11.5k/46k tokens, 128 output tokens, greedy, 3 reps, median):
| prompt tokens | v20 control TTFT / prefill tok/s / decode tok/s | v19b hotsplit TTFT / prefill / decode |
|---|---|---|
| 2,952 | 2.76 s / 1,071 / 31.3 | 2.52 s / 1,170 / 35.3 |
| 11,521 | 9.15 s / 1,259 / 31.2 | 8.55 s / 1,348 / 35.1 |
| 45,826 | 35.40 s / 1,295 / 31.0 | 34.01 s / 1,347 / 34.7 |
Decode +13% (31.2 → 35.1 at 11.5k), prefill +7%.
Agent fixture (tokens/s, warm runs r2 and r3; they agreed within 0.1):
| task | v20 control | v19b hotsplit |
|---|---|---|
| tool_json | 29.5 | 35.9 |
| code | 30.3 | 31.1 |
| shell_ops | 28.6 | 35.7 |
| structured | 30.0 | 34.1 |
| prose | 30.3 | 30.1 |
Gains are largest on tool, shell, and structured calls — agent-shaped traffic, matching the turns the hot list was ranked on. Prose is unchanged.
The honest caveat: on the synthetic prose knee prompt hotsplit is ~5% slower at C1 (28.2–28.5 vs 30.0), C8 57.8. The hot list is workload-specific. That prompt is 192-token prose (“paragraph about the number N”), ignore_eos, short prompts; six clean C1 samples are 28.2–28.5 against v20 control 30.0 ×6 (a first sweep read 20.4, runs 27.8 / 12.9, and that first run is a warmup outlier). On agent-shaped and long-context streaming, hotsplit is 13–25% faster. v20 control reproduces v14 (C1 30.2, C8 56.2) without either patch.
The first full boot (v19) was OOM-killed during the split. It launched with the old lane's cudaHostRegister-patched uva.py, whose freed buffers did not return host memory (~3 GiB/layer leak; host avail 82 → 36 → 2.6 GiB at 10/20/30 layers). The fix is stock uva.py plus VLLM_WEIGHT_OFFLOADING_DISABLE_PIN_MEMORY=1 (exact cudaHostAlloc path), an explicit scale free, and a host-memory floor that leaves remaining layers stock instead of dying. v19b then split 69/69 layers in 33 s.
Methodology correction: my pre-control reading that hotsplit was neutral was wrong — it came from a cold fixture run plus a synthetic prose sweep; the matched warm A/B overturned it.
5:05 PM CDT: mixed ranking removes the prose penalty, and a profile says where the rest goes
v21 re-ranks the hot list with the agent-turn decode counts plus the first (prose-leaning) histogram at weight 0.25, same 141.8 GiB HBM budget. Held-out agent decode coverage drops slightly, 62.2% → 61.0%. Warm, same recipe otherwise:
| v20 control | v19b (agent-ranked) | v21 (mixed-ranked) | |
|---|---|---|---|
| Decode, 11.5k-token prompt | 31.2 | 35.1 | 36.3 |
| tool_json | 29.5 | 35.9 | 35.7 |
| shell_ops | 28.6 | 35.7 | 35.4 |
| structured | 30.0 | 34.1 | 34.8 |
| code | 30.3 | 31.1 | 31.9 |
| prose (fixture) | 30.3 | 30.1 | 31.6 |
| Synthetic prose knee prompt, C1 | 30.0 | 28.2–28.5 | 29.6–30.0 |
| C8 aggregate | — | 57.8 | 60.8 |
v21 is the lane: agent traffic keeps its gain, the prose penalty is gone, and C8 is the best number this box has produced for Pro.
Torch-profiler trace of 64 decode tokens on v21 (C1, CUDA graphs on): 28.8 ms per token, GPU busy 96% of it, so launch overhead is not the problem. Marlin routed experts take 17.3 ms per token (62%), dense FP8 GEMMs 5.8 ms (21%), MoE routing/align/sum 1.6 ms, attention 1.1 ms. Splitting the Marlin time by hot and cold set: hot w13+w2 3.4 ms per token, cold w13+w2 14.0 ms. The cold set carries about 39% of routed traffic and costs about 80% of the expert time — roughly 6× the cost per unit of traffic. The remaining lever is still residency (a bigger hot budget, traded against KV) or a faster cold path, not kernels or scheduling.
/model mimo). Through the real Hermes harness on the serving boot: 10/10 tool-call turns, 10/10 correct. Still pending on the card: a full-depth teacher-forced Δlogprob against the no-hotsplit control and a public tool-call suite. Done September 24: both ran and passed. See the top of this post.5:50 PM CDT: a bigger hot budget, live counts, and where the dense time goes
v22 moves 11 GiB from KV cache to the hot set (hot budget 141.8 → 152.8 GiB; 8,692 of 26,496 cells hot). KV drops from 513,612 to 302,368 tokens, still 1.15× one 256k-token request. Warm, tok/s:
| v21 (141.8 GiB hot) | v22 (152.8 GiB hot) | |
|---|---|---|
| Decode, 3k / 11.5k / 46k-token prompt | 36.4 / 36.3 / 35.7 | 37.5 / 37.4 / 36.9 |
| tool_json / shell / structured | 35.7 / 35.4 / 34.8 | 36.6 / 36.4 / 35.9 |
| code / prose | 31.9 / 31.6 | 32.6 / 32.7 |
| Synthetic prose, C1 | 29.6–30.0 | 29.7–30.1 |
| C8 aggregate | 60.8 | 63.7 |
About +1 tok/s per 11 GiB moved, consistent with the profile: every cell promoted is a cold-path read removed. The box is single-user; 302K KV tokens is enough, so v22's budget is the lane.
v23 is v22 plus a live routing counter inside the captured decode graph (index_add_ into a preallocated device tensor, decode-sized steps only, snapshotted every 10 minutes). Cost: 0.3–0.6 tok/s (decode 36.9–37.1 vs 37.4–37.5). A weekly job merges the live counts into a candidate hot list, refuses below 50,000 decode tokens per layer, and never restarts the lane; the new list applies on the next boot. v23 is serving.
Dense GEMMs, from the same trace: per layer, the BF16 o_proj (nvjet split-K, 36.1 µs) and the FP8 qkv_proj (CUTLASS blockwise, 35.9 µs) together cost 5.0 ms per token. By bytes that is about 5.3 TB/s and 4.4 TB/s: both already bandwidth-bound, so a different kernel will not help. The one lever is the checkpoint: o_proj is listed in ignored_layers and stays BF16, 13.1 GiB read per token. Quantizing it to FP8 would save roughly 1.2 ms per token. That changes the model, not the serving recipe, and needs a quality gate before it is worth a boot.
Upstream: the split, held-out ranking data, parity, matched A/B, and the cold-bank cost ratio were posted as data on the existing vLLM RFC for expert-granular residency, #57794, rather than as a duplicate issue.
11:40 PM CDT: long context, 65K to 254K tokens
Asked for on X (“Can you do long context pls?”). This ran as a client benchmark on the live v23 lane: no restart, 262,144-token max context, a 302,368-token KV pool. Filler is real Python standard-library source, sized with the server’s own tokenizer. Every prompt starts with a unique nonce, so the prefix cache cannot help. At each size, a random code is planted at 10%, 50% and 90% depth and the model is asked for it; a fourth prompt measures decode on a 256-token reply. Thinking is off, T=0, one request at a time.
| Prompt tokens | Needles 10/50/90% | TTFT | Prefill | Decode after TTFT |
|---|---|---|---|---|
| 11.5K (reference) | — | 8.4 s | 1,376 tok/s | 36.9–37.1 tok/s |
| 62K–65K | 3/3 | 47–49 s | 1,326–1,350 | 34.0 |
| 131K | 3/3 | 99.8 s | 1,310–1,312 | 34.3 |
| 196K | 3/3 | 153–154 s | 1,276–1,285 | 33.3 |
| 254K | 3/3 | 201 s | 1,261–1,262 | 33.8 |
At 254K, decode is 9% below the 11.5K number and prefill is 8% below. That is expected: decode on this lane is bound by the cold expert bank, not attention. The cost of long context here is the wait before the first token: 3 minutes 21 seconds at 254K. All 12 needles came back exact.
My first pass at 196K and 254K overlapped another client on the same lane for about 25 minutes. That showed up as 21.8 tok/s decode and a 306 s TTFT. I re-ran both sizes on an idle lane (the table above) and kept the contended rows as receipts. They are labeled, not averaged in. One planted fact is the easy long-context test: it shows the lane attends across 254K tokens. It does not measure reasoning or summarizing at that length, and that stays pending. The KV pool holds one 254K request; two at once need the stock-equal budget variant (514K). Script, rows, and receipts: longctx.md in the recipe.
12:50 AM CDT: 1M context, and what it costs
The model supports 1M tokens (max_position_embeddings 1,048,576), but the recipe served 262K. That was a mistake in the recipe, not a model limit. Only 10 of the 70 layers use full attention; the other 60 look back only 128 tokens. So KV costs about 55 KB per token, and each GiB of hot experts traded away buys about 19K tokens of context. v24 is v23 with two changes: --max-model-len 1048576 and a hot budget of 110 GiB, down from 152.8. The boot log shows a KV pool of 1,209,097 tokens, 1.15× one 1M request.
| v23 (262K, 152.8 GiB hot) | v24 (1M, 110 GiB hot) | |
|---|---|---|
| Decode after TTFT, 3K / 11.5K / 46K prompt | 37.5 / 37.4 / 36.9 | 33.2 / 33.0 / 32.7 (−12%) |
| tool_json / shell / structured | 36.6 / 36.4 / 35.9 | 32.7 / 32.5 / 31.7 |
| code / prose | 32.6 / 32.7 | 29.5 / 29.0 |
| Prefill, 11.5K prompt | 1,376 tok/s | 1,235 |
| 65K: needles, decode | 3/3, 34.0 | 3/3, 32.0 |
| 524K: needles, TTFT, decode | (does not fit) | 3/3, 489–496 s, 28.6 |
| ~1.04M | (does not fit) | 3/3, 1,101 s, 25.7 (measured September 24) |
Before the boot I estimated −7% (about 34.9 tok/s), assuming speed scales linearly with the share of traffic served from HBM. The boot measured −12%. The estimate was wrong, and I don’t yet know why the loss is larger.
I stopped the 1M run during its first 1.04M-token prefill. Each 1M prompt costs about 17 minutes of full GPU, and nobody needed that number tonight. So 524K is the longest prompt measured: all 3 needles found, 8 minutes 10 seconds to the first token, then 28.6 tok/s. The lane accepts 1,048,576-token requests; recall and speed at 1M are unmeasured and marked pending in the recipe. Corrected September 24, 2026: measured during the promotion run: 3/3 needles at 1.04M, 18.4 minutes to the first token, then 25.7 tok/s.
James chose to keep v24 as the serving lane: 12% slower on every turn, in exchange for the model’s full context. v23 is kept as the short-context speed variant (launch-hotsplit.sh v23 152.8 262144). Rows and receipts: longctx.md in the recipe.
Sent upstream
- vLLM PR #58142 (vllmellm): validation comment — the fused-qkv pairing fix, confirmed on a second hardware/loader/model with the op-by-op diff. https://github.com/vllm-project/vllm/pull/58142
- vLLM issue #58031: SM103 TRT-LLM MXFP4 autotune timings and the Marlin workaround. https://github.com/vllm-project/vllm/issues/58031
- vLLM issue #58178 (mine): UVA offload host-memory design, with a same-day correction after re-reading main — the re-offload path already existed; the real defect is power-of-two pinning. https://github.com/vllm-project/vllm/issues/58178
- vLLM PR #58184 (mine): skip fused fp8 qkv_proj tensors for layers the model does not have — makes
--hf-overrides num_hidden_layerstruncation work on MiMo-V2, which is what made the minute-scale bisection above possible. https://github.com/vllm-project/vllm/pull/58184 - vLLM PR #58185 (mine): UVA offload allocates exact-size pinned host memory instead of
Tensor.pin_memory(). Measured on a 16-layer, 40 GiB-offloaded boot: 90.3 GiB host used before, 58.4 GiB after, per-layer residuals bit-identical. https://github.com/vllm-project/vllm/pull/58185
Reproduce (as of 10:10 AM CDT, default loader, Marlin)
IMAGE=vllm/vllm-openai:nightly-d05da62e9ccdf8e342b15bf6785d83224cc165af   # 0.29.1rc1.dev422, post PR #57784
# do NOT use --load-format runai_streamer: zeroes fused-qkv fp8 weights on this model
docker run -d --gpus all --ipc host --network host --ulimit memlock=-1 --cap-add IPC_LOCK \
  -v /models/milo/MiMo-V2.6-Pro-RL:/model:ro \
  -v $PWD/patch/uva.py:/usr/local/lib/python3.12/dist-packages/vllm/model_executor/offloader/uva.py:ro \
  -v $PWD/patch/mxfp4.py:/usr/local/lib/python3.12/dist-packages/vllm/model_executor/layers/quantization/mxfp4.py:ro \
  -e VLLM_USE_DEEP_GEMM=0 \
  $IMAGE --model /model --served-model-name mimo26-pro --trust-remote-code \
  --tensor-parallel-size 1 --moe-backend marlin \
  --offload-backend uva --cpu-offload-gb 320 \
  --cpu-offload-params routed_experts.w13_weight routed_experts.w2_weight \
  --max-model-len 262144 --max-num-seqs 8 --max-num-batched-tokens 2048 \
  --gpu-memory-utilization 0.96 \
  --compilation-config '{"cudagraph_mode":"FULL_DECODE_ONLY"}' \
  --tool-call-parser mimo --reasoning-parser mimo --enable-auto-tool-choice \
  --generation-config vllm --port 30007
v14 is the boot that talks: default safetensors loader, no streamer. Both patches are still bind-mounts over the stock image; nothing is rebuilt. The Marlin flags above are what the documented working V2.6 serves use (PR #57784 launch lines; tonyd2wild's 2x DGX Spark Flash-RL serve). They end the autotune. They were not the garbage fix. The comment in the block is the fix: do not pass --load-format runai_streamer.
What comes next, in order
- v14 bound at 9:48 AM CDT and the tokens are sane. The blocker was
--load-format runai_streamer, not stock vLLM at TP1, not autotune, and not offload. The 6 AM QKV pre-shard note was a hypothesis, and it was wrong. The C1–C16 knee sweep started at 9:49 AM CDT and is not done. First decode numbers: C1 30.2 tok/s, knee at C8 with 56.2 aggregate (table below). - Expected ceiling before any placement work: ~6.9 GiB of expert reads from Grace per token (46 of 69 layers × 8 experts × 19.1 MiB) at k=0, at ~340 GiB/s, is ~18 ms of fetch per step. Call it 35–45 tok/s single-stream if nothing else is broken. That is a prediction, not a measurement; it gets replaced.
- Done: routed-expert histogram, hotsplit, mixed ranking, decode profile, a bigger hot budget (v22), a live routing counter with a weekly re-rank (v23), and the dense-GEMM check. Long context to 254K measured, then 1M served as v24 (above; 1M recall 3/3, measured September 24). Verified September 24: full-depth teacher-forced gate and BFCL against the stock-placement control (top of post). Next: a teacher-forced quality gate for FP8
o_proj, and applying the first live re-rank once 50,000 decode tokens per layer have accumulated. - DFlash on the omni class, then a k-sweep. Flash-RL as the all-HBM control lane. A diagnostic Flash-RL boot on this box was already sane; it is not a lane.
Two things worth saying plainly
The autotune trap: last night's py-spy reading was real — 52–66 ms per call at the 8192-token profile, 100 minutes, no cache written. Corrected September 23, 2026: an earlier version of this paragraph said FlashInfer's trtllm_fp4_block_scale_moe cubin is sm_100a-only and wedges on SM103. That was wrong. The op runs from fused_moe_trtllm_sm100.so, which carries sm_103a cubins, and the claim was withdrawn on vLLM issue #58031. Our own DeepSeek-V4.1-Flash logs on this box point at expert placement instead of the GPU generation: same GB300, same op, same vLLM nightly (dee37d89), same 21 token buckets. Stock whole-layer UVA offload (--cpu-offload-gb 60) spent 71 minutes in one tuning pass of this op; with our pin-hot-experts placement hook (--cpu-offload-gb 54, the only other launch-arg difference) the same pass took 8 minutes. Across all our DSV4.1 boots, stock placement tuned in 72–77 minutes and hook placement in 15–17. The mechanism is not isolated yet; host-resident expert reads during tuning are the leading suspect. Every documented working V2.6 serve — the launch lines in vLLM PR #57784, and tonyd2wild's 2x DGX Spark Flash-RL serve — uses --moe-backend marlin and VLLM_USE_DEEP_GEMM=0. With Marlin the same autotune takes 9 seconds and reports “Saved 0 configs”. v10, still on the auto-backend, did bind at 2:09 AM CDT after about two hours, and the tokens were garbage.
Second, both patches are bugs in stock vLLM for any UVA-offloaded MXFP4 model whose per-layer tensors are not a power of two — that is most of them. They will be filed upstream with the recipe. They are not the cause of the garbage. v13 returned the same string because it still loaded with --load-format runai_streamer, as every full-Pro boot from v3 through v13 did. v14 drops that flag. The tokens are sane.